Can coding agents recreate financial widgets from a screenshot?
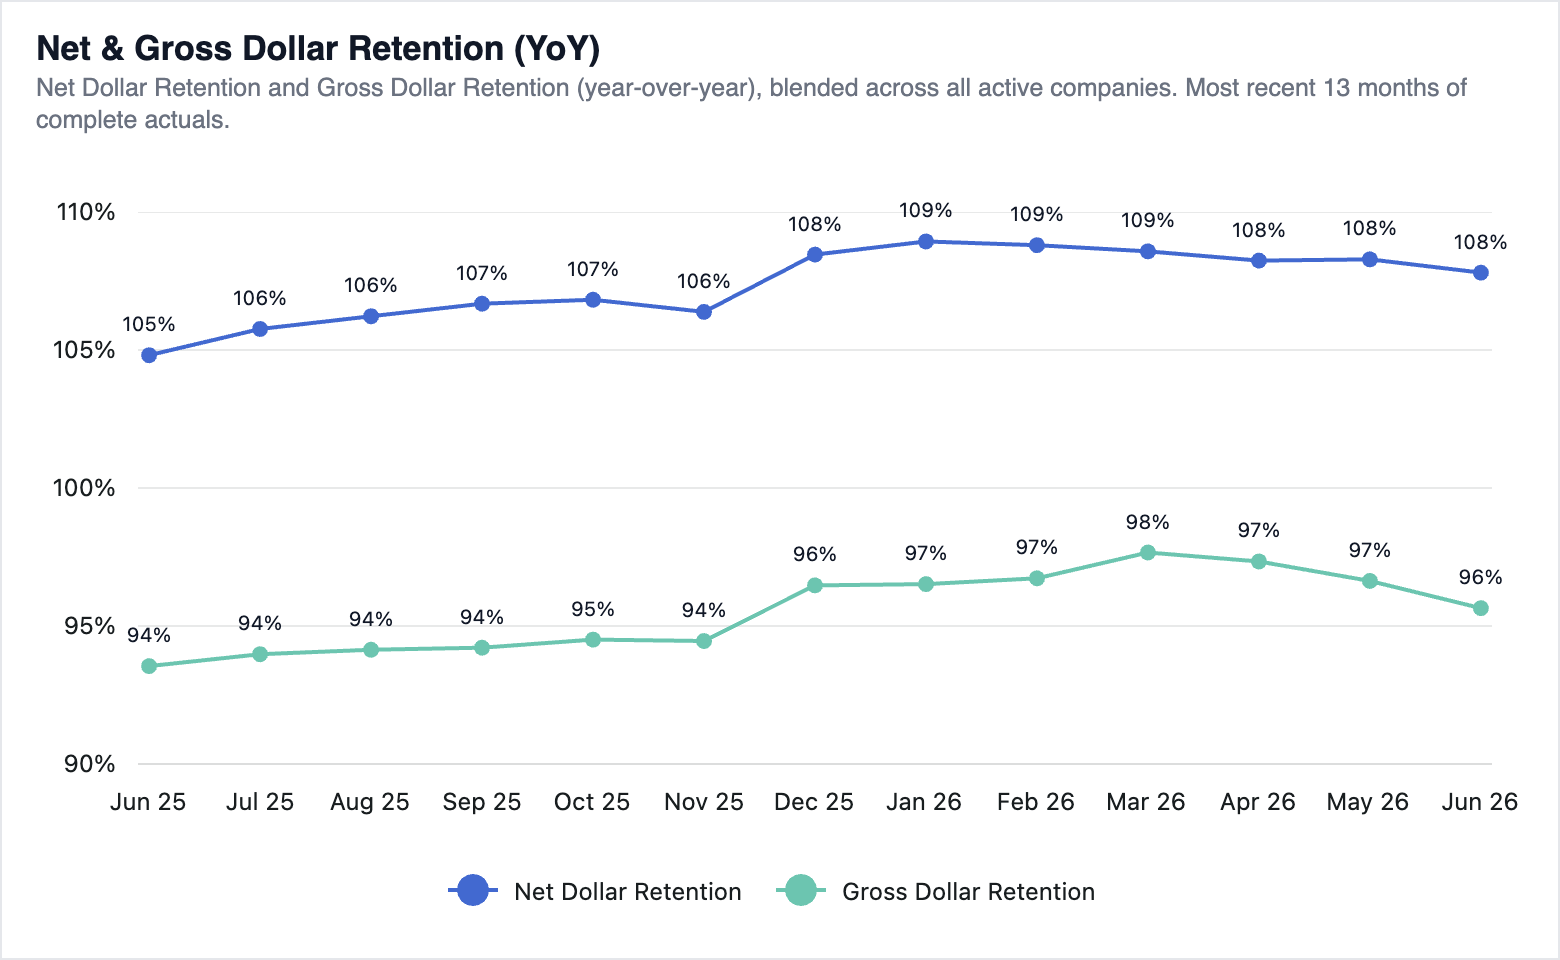
Based on reporting widgets from a proprietary financial analysis platform and framework for a private equity business, PlotterBench asks agents to rebuild a live financial chart from a screenshot. The agent has to work out the metric, time grain and reporting window from the image and express them as SQL and a chart config. We grade what the chart draws, and each task represents a distinct graph input.
Financial analytics · Multimodal
- Tasks
- 10
- Public tasks
- 10
- Models evaluated
- 4
- Published trials
- 40
- Leading model
- Muse Spark 1.3 ContributorOpenCode
- Leading mean reward
- 70.9%± 7.6 pp
- Mean reward
- Average of task means across the task versions that match the dataset’s rules.
- ± SE
- Standard error across task means; directional when a dataset has few tasks.
| Model · harness | Mean reward | ± SE | Tasks | Trials |
|---|---|---|---|---|
| Muse Spark 1.3 ContributorOpenCode | 70.9%Task means: 30.7%, 35.0%, 56.0%, 58.0%, 84.0%, 84.0%, 88.0%, 89.7%, 91.0%, 93.0%. | 7.6 pp | 10 / 10 | 30 |
| GPT 5.6 SolOpenCode | 59.3%Task means: 51.0%, 67.5%. | 8.3 pp | 2 / 10 | 4 |
| gemini-3.1-pro-previewOpenCode | 40.8%Task means: 32.0%, 49.5%. | 8.8 pp | 2 / 10 | 4 |
| GPT 5.6 LunaOpenCode | 39.0%Task means: 32.0%, 46.0%. | 7.0 pp | 2 / 10 | 2 |
How PlotterBench works
1 · The agent gets a screenshot
A real reporting-pack chart, recreated in an anonymized environment. The instruction is a few sentences; house conventions live in the repo docs.
2 · It ships a widget definition
One JSON object against a typed widget contract: a SQL query over the warehouse plus serializable AG Charts config. Every key the config references must come out of the query.
{
  "widgetId": "agChart",
  "config": { "chartOptions": {
    "axes": { "y": { "label": { "format": ".0%" } }, … },
    "series": [ { "type": "line",
      "xKey": "periodLabel", "yKey": "ndr",
      "stroke": "var(--chart-series-1)",
      "appLabel": { "valueKey": "ndrLabel" } }, … ]
  } },
  "query": { "text": "with coverage as (
    -- latest month every company has actuals
    … ) select … from metrics.metric_points" }
}
3 · Grading is what the chart draws
Execute → Extract → Compare → Perturb
Both definitions run against the same warehouse and are compared by what they render; then new data lands and both re-run. Below: gpt-5.6-luna scoring 0.28.

Result 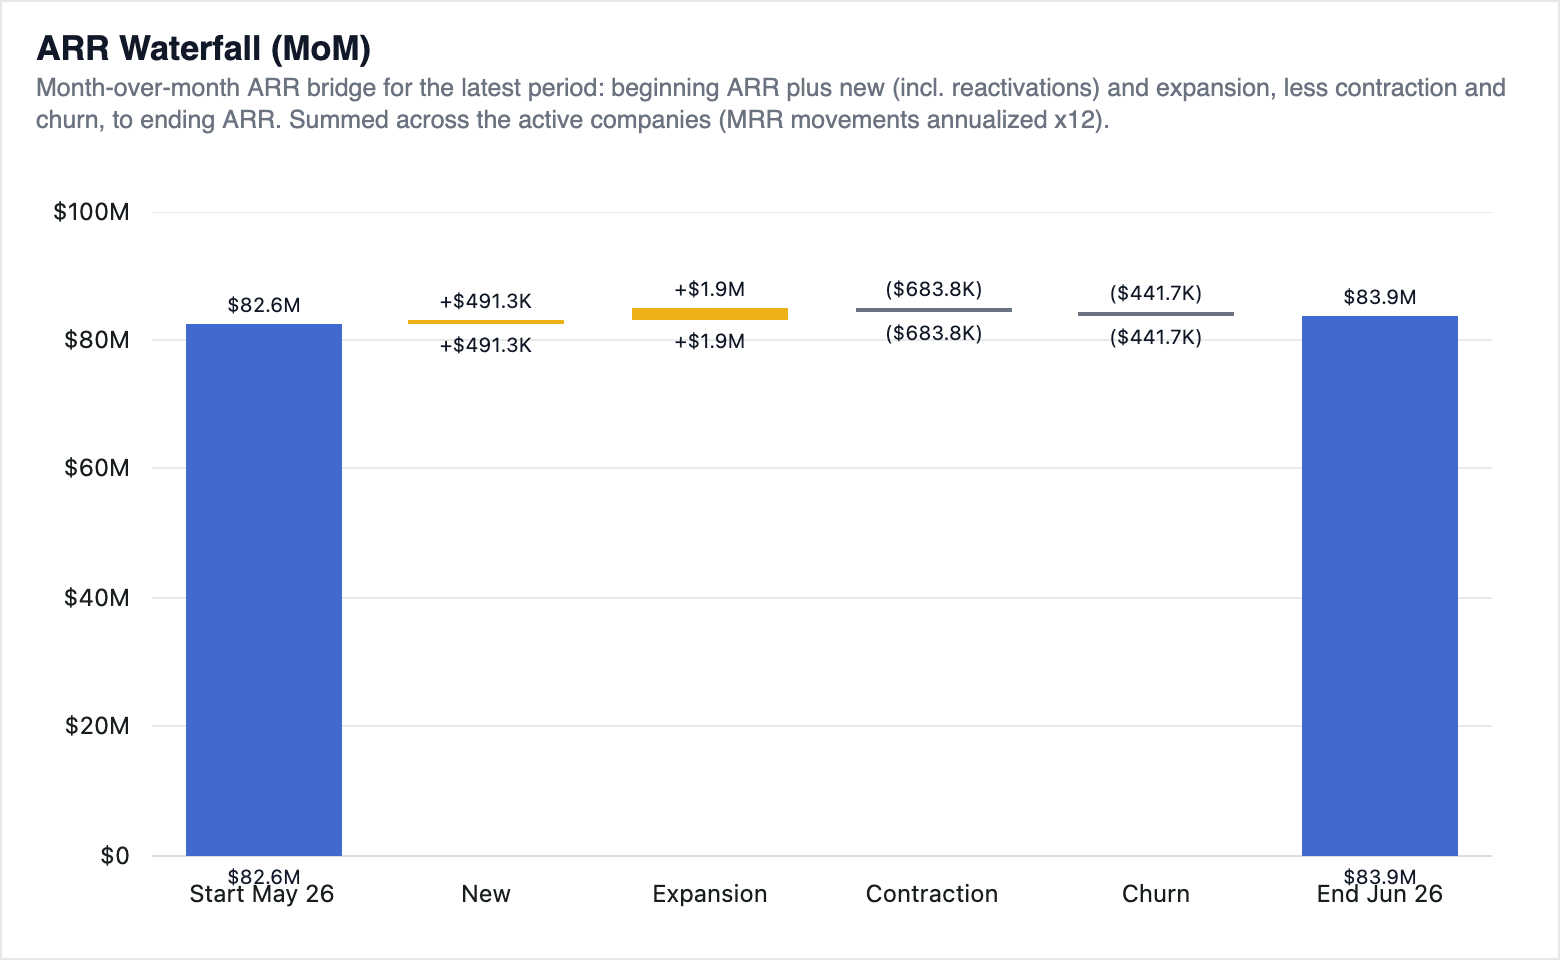
Expected
Pass rate (%) · 0.0% of 40 scored trials pass
Median steps per trial · 10 tasks
Elapsed runtime · 40 timed trials
| Public trials | ||||
|---|---|---|---|---|
| v0.1.1 | 93.0%3 attempts | 0 / 3 | 6m 50s | |
| v0.1.1 | 84.0%3 attempts | 0 / 3 | 3m 45s | |
| v0.1.1 | 36.3%8 attempts | 0 / 8 | 8m 5s | |
| v0.1.1 | 84.0%3 attempts | 0 / 3 | 6m 26s | |
| v0.1.1 | 91.0%3 attempts | 0 / 3 | 4m 17s | |
| v0.1.1 | 89.7%3 attempts | 0 / 3 | 8m 43s | |
| v0.1.1 | 56.8%8 attempts | 0 / 7 | 5m 33s | |
| v0.1.1 | 56.0%3 attempts | 0 / 2 | 7m 32s | |
| v0.1.1 | 88.0%3 attempts | 0 / 3 | 6m 0s | |
| v0.1.1 | 35.0%3 attempts | 0 / 3 | 11m 17s |